healthcheck-service
The smallest thing that answers "is it up?".
 Go
 Docker
 View source
- 502
- Lines of Go
- 2
- Third-party deps
- 1
- Endpoints watched
The problem
Uptime monitoring is priced per monitor, and a small service that needs watching is often cheaper to run than the thing watching it. I wanted one endpoint checked on a schedule, an alert when it stopped answering, and nothing else.
What I built
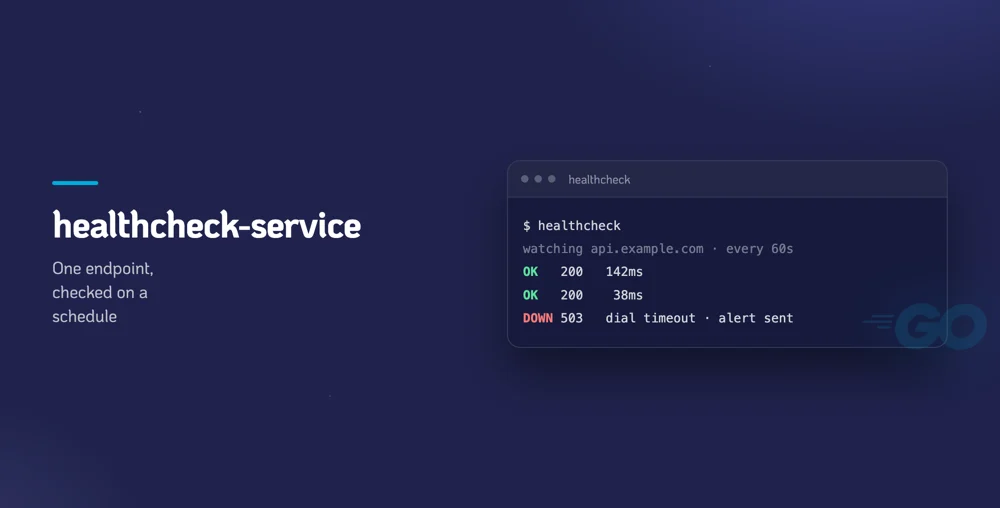
A Go binary in about five hundred lines and two third-party dependencies. It calls one configured endpoint every minute, and on a transport error or a non-200 response it posts to Slack and sends an email. Configuration is environment variables only; the whole thing ships as a multi-stage Docker build producing a static binary on Alpine, running as a non-root user.
Decisions I'd defend
The scheduler is fourteen lines: run once, then a ticker. There is no job framework, no queue and no persistence, because a monitor that needs its own infrastructure to stay up has inverted its own purpose.
The container build is the part I would defend hardest, because it is the part that usually goes wrong. CGO off, trimmed and stripped, a static binary on a minimal base with CA certificates added explicitly, running as a fixed non-root uid. The build context excludes every environment file with a single negation for the example, so a secret cannot end up in a layer.
The tradeoffs
This is a deliberately small tool and it is worth being precise about what that costs. One endpoint per process, a fixed one-minute interval, a fixed request method, no failure threshold so a single blip alerts, and no recovery notification when it comes back. Nothing is persisted, so there is no history and no uptime percentage.
It has no tests. Its successor, supabase-pings, is where most of these were fixed, and the diff between the two is the honest version of what I learned writing it.
Where it is now
Public, MIT licensed, and doing the one job it was written for. The README carries its own limitations section, which matches the code.